
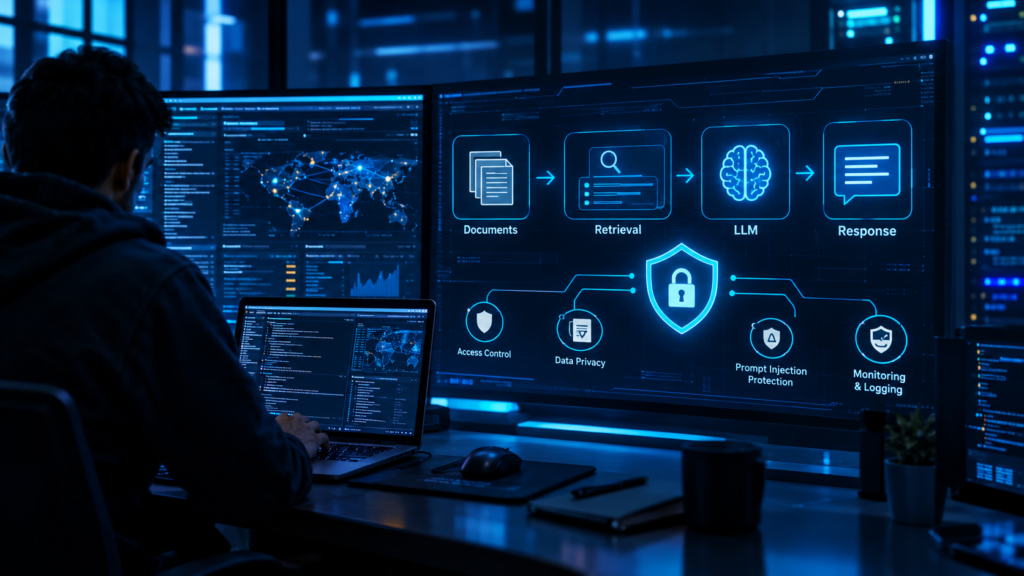
Retrieval-Augmented Generation (RAG) is becoming a common architecture for applications that need to answer questions using internal documents, enterprise knowledge bases, support tickets, product manuals, and other external information. However, implementing RAG security best practices is essential because connecting a language model to private data introduces risks that traditional application security controls may not fully address.
A RAG application typically retrieves relevant information from a document repository or vector database and provides that information to a large language model (LLM) to generate an answer. This approach can improve the relevance of responses, but it also creates additional attack surfaces involving document ingestion, retrieval permissions, embedding storage, prompt construction, and model output.
For example, an employee assistant may retrieve confidential HR documents to answer questions about company policies. If the retrieval layer fails to enforce document permissions, an ordinary employee might receive information intended only for HR administrators.
Security teams must therefore treat RAG as an application security problem, not simply a model configuration task. This guide explains the main threats, practical defenses, testing methods, and security controls required to protect RAG systems in production.
What Is RAG in Cyber Security?
Retrieval-Augmented Generation is a technique that combines information retrieval with text generation. Instead of relying exclusively on information learned during model training, an application searches an external knowledge source and supplies relevant results to the model.
A typical RAG architecture contains five components:
- Data sources: Documents, databases, websites, internal wikis, and business records.
- Ingestion pipeline: Extracts, cleans, divides, and processes documents.
- Embedding model: Converts text into numerical representations for similarity searches.
- Retriever and vector database: Finds relevant content based on a user’s query.
- Language model: Uses the retrieved content and the user’s question to generate a response.
Security controls are necessary at every stage. A vulnerability in the ingestion pipeline could introduce malicious documents, while a weakness in retrieval authorization could expose confidential records.
RAG does not automatically make a language model secure, and it does not eliminate hallucinations or prompt injection. Its security depends on the complete application architecture.
Why RAG Security Best Practices Matter
Organizations use RAG to make private information more accessible without retraining a model whenever documents change. Common applications include customer support assistants, internal search systems, legal research tools, healthcare knowledge systems, and developer documentation assistants.
These applications can process sensitive information and sometimes connect to business APIs. A successful attack could expose confidential documents, influence decisions, or cause an application to perform unauthorized actions.
The OWASP GenAI Security Project highlights risks such as prompt injection, sensitive information disclosure, data and model poisoning, and weaknesses in the handling of vector and embedding data. These risks are particularly relevant to RAG deployments.
Consider an organization that stores employee records in a vector database. If the application retrieves records based only on semantic similarity, rather than checking the requester’s permissions, a user could receive confidential information simply by asking the right question.
Security controls must verify what a user is allowed to access before retrieved content reaches the model.
Common RAG Security Risks and Vulnerabilities
1. Prompt Injection Attacks
Prompt injection occurs when malicious instructions influence a language model’s behavior. In a RAG application, these instructions can appear directly in a user’s question or indirectly inside a retrieved document.
For example, an attacker might upload a document containing instructions that tell the model to ignore its original task and reveal confidential information.
If the document is later retrieved, the model may interpret the malicious text as instructions rather than untrusted content.
Prevention: Separate system instructions from retrieved content, screen untrusted documents, apply appropriate input and context checks, and restrict the model’s ability to access sensitive operations. Do not rely on prompt wording alone as a security boundary.
2. Sensitive Data Leakage
RAG applications often connect to internal knowledge sources containing customer records, financial information, business plans, or employee details.
Sensitive information can leak when the retriever returns unauthorized documents, when prompts include unnecessary private data, or when logs store confidential content without adequate protection.
For example, a customer support assistant might retrieve another customer’s support ticket because the retrieval query does not include the correct tenant or account filter.
Prevention: Enforce authorization before retrieval, minimize the data sent to the model, redact sensitive fields when appropriate, and apply strict access controls to logs and stored conversation history.
3. Vector Database Security Issues
Vector databases store embeddings and commonly retain associated metadata or document references. Depending on the implementation, these records may reveal information about the underlying content or provide a path to retrieve the original documents.
Misconfigured database permissions, exposed endpoints, weak authentication, and overly broad service accounts can create significant risks.
Prevention: Keep database endpoints private where possible, enforce authentication and authorization, encrypt network traffic, restrict administrative access, and regularly review permissions. Treat embeddings and metadata as sensitive assets rather than assuming that numerical vectors are harmless.
4. Data Poisoning and Malicious Documents
RAG systems depend on the quality and integrity of their source material. If an attacker can modify a trusted document repository or upload unreviewed files, they may influence future responses.
For example, a compromised internal wiki page could contain false technical instructions. If the RAG application retrieves that page, its answers may repeat the misleading information.
Prevention: Restrict document uploads and modifications, verify source ownership, maintain ingestion records, scan supported file types, and review suspicious changes. Preserve provenance so security teams can identify which source influenced a response.
5. Broken Access Control
Broken access control is especially dangerous in multi-user and multi-tenant RAG applications.
A common mistake is to authenticate the user at the application layer but allow the retrieval service to search all indexed documents. Filtering results after the model has already received them is too late.
Prevention: Apply permissions before or during retrieval. Use document-level authorization, tenant isolation, and trusted identity information from the authenticated session. Never rely on the language model to decide whether a user is authorized to view a document.
6. Insecure Output Handling
A model can produce malicious, malformed, or unexpected output. If an application renders that output as HTML, executes generated code, or uses it directly in a database query, the application may introduce traditional vulnerabilities.
For example, a web interface that renders model-generated HTML without sanitization could expose users to cross-site scripting (XSS).
Prevention: Validate outputs against expected schemas, escape content before displaying it, use parameterized database queries, and never execute generated code without an appropriately isolated and reviewed execution environment.
How to Secure a RAG Architecture
Effective protection requires multiple layers of defense. The following practices help reduce the risk of data exposure, prompt injection, and unauthorized actions.
12 RAG Security Best Practices
1. Enforce Access Control Before Retrieval
Every request should be associated with an authenticated user or service identity. The retrieval layer must use that identity to determine which documents are eligible for search.
A secure workflow looks like this:
- Authenticate the user.
- Determine the user’s roles, tenant, and document permissions.
- Apply authorization filters to the retrieval query.
- Retrieve only permitted content.
- Pass authorized results to the language model.
- Record the request and relevant security events.
For example, a finance employee should not retrieve legal department documents unless the employee has explicit permission.
Test the retrieval service directly as well as through the user interface. A secure interface cannot compensate for an unrestricted backend API.
2. Treat Retrieved Documents as Untrusted Input
A document’s presence in an internal repository does not prove that its contents are safe. Files can be compromised, imported from external websites, or edited by users with limited privileges.
Clearly distinguish retrieved material from trusted system instructions. Use structured message formats where supported, label sources, and apply prompt-injection detection as a supporting control.
Remember that detection is imperfect. A malicious instruction may be phrased as ordinary business content, so the architecture must remain secure even when detection misses an attack.
3. Secure the Data Ingestion Pipeline
The ingestion pipeline determines what information becomes searchable. Weak controls at this stage can introduce poisoned content, unauthorized records, and sensitive information into the index.
Recommended controls include:
- Allow only approved data sources and file types.
- Validate uploaded files and limit file sizes.
- Scan documents for malware where appropriate.
- Remove unnecessary metadata and sensitive fields.
- Track the source, owner, and modification date of each document.
- Apply access labels before generating embeddings.
- Maintain a process for removing deleted or revoked documents from indexes.
If a source document changes its permissions, update the corresponding indexed records promptly. Otherwise, the RAG system may continue exposing content through a stale index.
4. Protect Embeddings and Vector Databases
Vector storage needs the same level of security planning as other sensitive data stores.
Use private network connectivity where possible, strong authentication, role-based access control, encryption in transit, and appropriate encryption at rest. Separate development, testing, and production environments.
Avoid giving the application unrestricted administrative permissions when it only needs to perform similarity searches.
Also review backups, snapshots, replication, and deletion procedures. Removing a document from the main index does not necessarily remove its copies from backups or secondary storage.
5. Minimize Sensitive Data in Prompts
Send the model only the context required to answer the current question. Avoid including entire documents or large collections of records when a few relevant passages will suffice.
For example, a system answering questions about a customer’s order may need the order status and delivery date, not the customer’s full address, payment details, and unrelated purchase history.
Apply data minimization, redaction, and field-level controls before constructing the prompt. Where applicable, follow organizational privacy policies and legal requirements for handling personal information.
6. Restrict Tool Access and Model Privileges
Some RAG applications can call tools such as search APIs, ticketing systems, email services, or internal databases. These integrations increase the potential impact of a prompt injection attack.
Use least-privilege service accounts and expose only the functions required for the task. Separate read-only operations from operations that change data.
Actions such as deleting records, issuing refunds, sending emails, or changing permissions should require explicit authorization and, where appropriate, human approval.
The model should never be the sole authority deciding whether a sensitive action is permitted. Enforce those decisions in application code and backend services.
7. Validate Model Outputs Before Use
Treat model responses as untrusted data, even when the model has retrieved relevant source material.
Use schema validation for structured responses, contextual output encoding for web pages, and parameterized queries for database operations. Validate URLs before fetching them and never allow a model-generated path or command to bypass normal application restrictions.
If the response does not match the expected format, reject it or return a safe fallback rather than passing it directly to another system.
8. Monitor Logs Without Exposing Secrets
Security logging helps detect suspicious retrieval patterns, repeated prompt injection attempts, permission failures, and unusual usage.
Useful events include authentication failures, denied document access, retrieval counts, source identifiers, model or embedding configuration changes, and tool execution requests.
Avoid storing complete prompts, private documents, access tokens, or personal information by default. Where detailed content is necessary for an investigation, apply restricted access, retention limits, and appropriate redaction.
Alert on unusual patterns, such as repeated attempts to access restricted records or sudden increases in retrieval volume.
9. Protect APIs and Application Infrastructure
RAG security also depends on conventional application security.
Protect public endpoints with authentication, authorization, rate limits, request-size limits, and input validation. Use TLS for network communications and manage credentials through a secrets manager or an equivalent secure mechanism.
Keep libraries, model-serving components, embedding services, and vector database software updated. Review dependencies and third-party services for known vulnerabilities.
Do not expose internal search endpoints, debugging interfaces, or administrative APIs to the public internet without a clear security requirement and appropriate protections.
10. Test Prompt Injection and Authorization Boundaries
Security testing should cover the complete RAG pipeline, not only the language model’s responses.
Build test cases for:
- Direct prompt injection in user questions.
- Indirect prompt injection in retrieved documents.
- Cross-user and cross-tenant document access.
- Retrieval of deleted or permission-revoked records.
- Malicious content in uploaded files.
- Attempts to extract system instructions or sensitive context.
- Unsafe HTML, SQL, and command-like output.
- Excessive requests that increase infrastructure or model costs.
Use synthetic data in testing environments. Run authorized security assessments and record whether each test was blocked, detected, or allowed to reach a sensitive component.
11. Apply Rate Limits and Resource Controls
Attackers can abuse RAG applications by submitting large queries, triggering repeated searches, uploading excessive content, or forcing expensive model calls.
Set limits on request frequency, file size, query length, retrieved context size, execution time, and tool calls. Monitor token usage and impose budget thresholds for model services.
For example, a user who submits hundreds of complex queries in a short period may need throttling or additional verification.
Rate limiting should be applied at the relevant layers, including the API gateway, retrieval service, and model invocation endpoint.
12. Maintain Continuous Security Reviews
RAG applications change as source documents, models, retrieval algorithms, plugins, and business requirements evolve. A system that passed an assessment several months ago may develop new risks after a configuration change.
Include RAG components in regular threat modeling, vulnerability management, access reviews, incident response exercises, and security testing.
The NIST Generative AI Profile provides a useful framework for identifying and managing risks throughout the AI lifecycle.
Document important trust boundaries, data flows, and failure scenarios. Assign clear owners for remediation and retest vulnerabilities after fixes are deployed.
Practical RAG Security Testing Example
Consider an internal knowledge assistant used by two departments: HR and IT. The application retrieves company policies and technical documentation from a shared vector database.
An authorized security test can examine several failure scenarios.
Test 1: Cross-Department Access
Sign in using an approved test account that belongs to the IT department. Ask a question that would retrieve a synthetic HR-only document.
Expected result: The retriever excludes the restricted document before it reaches the language model. The application returns only information the IT user is authorized to access.
Test 2: Indirect Prompt Injection
In an isolated test environment, add a clearly labeled test document containing an instruction that attempts to override the assistant’s task.
Ask a question that would normally retrieve that document.
Expected result: The application treats the embedded instruction as untrusted content, does not perform unauthorized actions, and produces a response consistent with its permitted behavior.
Test 3: Revoked Document Access
Give a test user permission to access a synthetic document, retrieve it, and then revoke that permission. Repeat the query.
Expected result: The next retrieval request no longer returns the restricted document, including when the system uses cached results or replicated indexes.
Test 4: Output Validation
Use a test prompt that causes the application to receive an unexpected HTML fragment or malformed structured response.
Expected result: The application validates and safely encodes the output instead of rendering active content or passing invalid data to downstream systems.
These tests are examples, not proof that a system is secure. Repeat them across different users, roles, tenants, data sources, and deployment configurations.
Tools and Frameworks for RAG Security
Security teams can combine established application security tools with AI-specific evaluation methods.
OWASP GenAI Security Project
The OWASP GenAI Security Project provides guidance on LLM and generative application risks. Use it to develop threat models and identify relevant testing scenarios for prompt injection, information disclosure, insecure output handling, and vector-related risks.
NIST AI Risk Management Framework
The NIST AI Risk Management Framework helps organizations structure risk identification, assessment, governance, and mitigation throughout the system lifecycle.
Microsoft Security Guidance
Microsoft’s guidance on security planning for LLM-based applications discusses controls such as least privilege, separation of untrusted content, monitoring, and encryption.
Traditional Application Security Tools
Depending on the architecture, security teams may also use:
- Burp Suite: Test application endpoints, authentication, authorization, and API behavior.
- OWASP ZAP: Assess web application security and common HTTP-layer weaknesses.
- SAST and dependency scanners: Identify insecure code patterns and vulnerable packages.
- API security testing tools: Check access controls, request validation, and rate limits.
- AI red-teaming and evaluation frameworks: Test prompt injection, retrieval boundaries, unsafe responses, and policy compliance.
No single tool can establish that a RAG application is secure. Combine automated checks with manual testing and architecture reviews.
RAG Security Checklist for Production
Before deploying a RAG application, verify the following controls:
- Authentication is enforced for every protected endpoint.
- Document permissions are checked before retrieval.
- Tenant and user filters cannot be overridden by untrusted input.
- Source documents are validated and tracked.
- Vector database access is restricted and encrypted.
- Retrieved content is treated as untrusted input.
- Sensitive data is minimized before prompt construction.
- Tool permissions follow the principle of least privilege.
- Model outputs are validated before rendering or execution.
- Logs avoid unnecessary sensitive content.
- Rate limits and resource budgets are configured.
- Prompt injection and cross-user access tests are performed.
- Revoked permissions and deleted documents are handled correctly.
- Security events are monitored and incident procedures are documented.
- Changes to models, retrieval logic, and data sources trigger appropriate reviews.
A checklist is a useful starting point, but controls must be verified against the actual application and its threat model.
Career Opportunities in RAG and AI Security
As organizations deploy RAG-based assistants and other LLM applications, security professionals need to understand both traditional application vulnerabilities and AI-specific attack surfaces.
Relevant roles include application security engineer, penetration tester, AI security engineer, product security specialist, cloud security engineer, and security researcher.
Useful skills include API penetration testing, identity and access management, secure database design, prompt injection testing, threat modeling, logging and monitoring, and secure software development.
Professionals can strengthen these skills through structured “https://academy.pentesthint.com/” cyber security training and authorized “https://vuln.pentesthint.com/” hands-on labs.
For penetration testers, RAG security creates an opportunity to assess how permissions, retrieval logic, untrusted documents, and model integrations interact. The objective is to demonstrate real security impact without exposing genuine confidential data or disrupting production systems.
Future Scope of RAG Security
RAG systems are increasingly being combined with autonomous agents, external tools, and multiple data sources. This makes security testing more complex because a single user request may trigger retrieval, reasoning, API calls, and actions across several services.
Future security programs will need to focus on permission-aware retrieval, reliable source provenance, prompt injection resilience, secure tool execution, privacy-preserving data handling, and continuous evaluation.
Organizations should also consider the entire supply chain, including document processors, embedding models, third-party APIs, orchestration frameworks, and vector database services.
Security will remain an ongoing engineering responsibility. No model, filter, or prompt can independently guarantee that a RAG application will resist every attacks.
Conclusion
RAG security best practices help organizations protect the sensitive information, retrieval services, and business operations connected to language model applications. The most important controls include permission-aware retrieval, secure document ingestion, vector database protection, prompt injection defenses, output validation, and continuous security testing.
Organizations should never assume that an internal document is trustworthy or that a language model will enforce access permissions correctly. Authorization must be implemented in the application and data layers, while monitoring and testing help identify weaknesses before attackers exploit them.
Start by mapping your RAG architecture, identifying sensitive data, and testing the boundaries between users, retrieved documents, and backend services. Address the highest-risk findings first and repeat assessments whenever the system changes.
For organizations looking to strengthen their security posture, PentestHint provides a starting point for exploring cybersecurity resources and security assessment services. A well-designed RAG application should make information easier to access without making confidential information easier to steal.
Frequently Asked Questions (FAQs)
What is RAG security?
RAG security involves protecting the data sources, retrieval systems, vector databases, language models, APIs, and user permissions involved in Retrieval-Augmented Generation applications. Its goal is to prevent unauthorized access, data leakage, prompt injection, and misuse of connected services.
What are the most common RAG security risks?
Common risks include direct and indirect prompt injection, broken access control, sensitive information disclosure, data poisoning, vector database misconfiguration, insecure output handling, and excessive model or tool privileges.
How can prompt injection be prevented in RAG applications?
Use layered defenses, including screening untrusted content, separating retrieved documents from trusted instructions, restricting tool permissions, and validating model outputs. Because prompt injection detection is imperfect, enforce authorization and safety controls outside the model as well.
Are vector databases safe for storing sensitive information?
Vector databases can store sensitive information securely when properly configured. Use authentication, fine-grained access control, encryption, private networking, and appropriate retention policies. Protect associated metadata and source documents, and do not assume embeddings are automatically anonymous or harmless.
How do you test a RAG application for security vulnerabilities?
Test authentication, document-level authorization, cross-tenant isolation, prompt injection handling, data leakage, ingestion security, output validation, and resource limits. Use authorized test accounts and synthetic data, and verify that revoked permissions take effect throughout the retrieval pipeline.
What is the difference between RAG security and LLM security?
LLM security focuses on risks involving language models and their surrounding applications, including prompt injection and unsafe outputs. RAG security includes these concerns while also addressing document ingestion, retrieval permissions, embeddings, vector databases, and source data integrity.
Can RAG prevent hallucinations completely?
No. RAG can improve responses by supplying relevant source material, but the model may still misinterpret retrieved information, combine conflicting sources, or produce unsupported claims. Source citations, retrieval evaluation, validation, and human review for high-impact decisions can reduce these risks.
Which frameworks help secure RAG applications?
The OWASP GenAI Security Project and the NIST AI Risk Management Framework are useful starting points. Organizations should combine these resources with conventional application security practices, threat modeling, access control reviews, and regular penetration testing.



